I want you to imagine a product with an average of 300 bugs a day. Bugs are fixed every day, and even more are added that same day. The Net Promoter Score (NPS), which measures how likely customers are to recommend the product, is literally below zero. There’s a new fire to fight every day. Every single day.
What I Saw When I Became CTO
Now imagine you’ve just become the CTO of that company. What would you do? I was the CTO of that company.
The very first thing you need to do is get hands-on. You have to be in the trenches to understand what’s going on. As CTO, you need to zoom out and see the process end to end. When something is failing, you also need to be able to zoom in and fix it.
When I started zooming in, I found three main issues.
The incentives and metrics rewarded closing tickets.
There was no proper software development life cycle.
Leadership underestimated how one decision affects another.
Now let’s dive into each of them.
The Problems
The Incentive System and the Metric
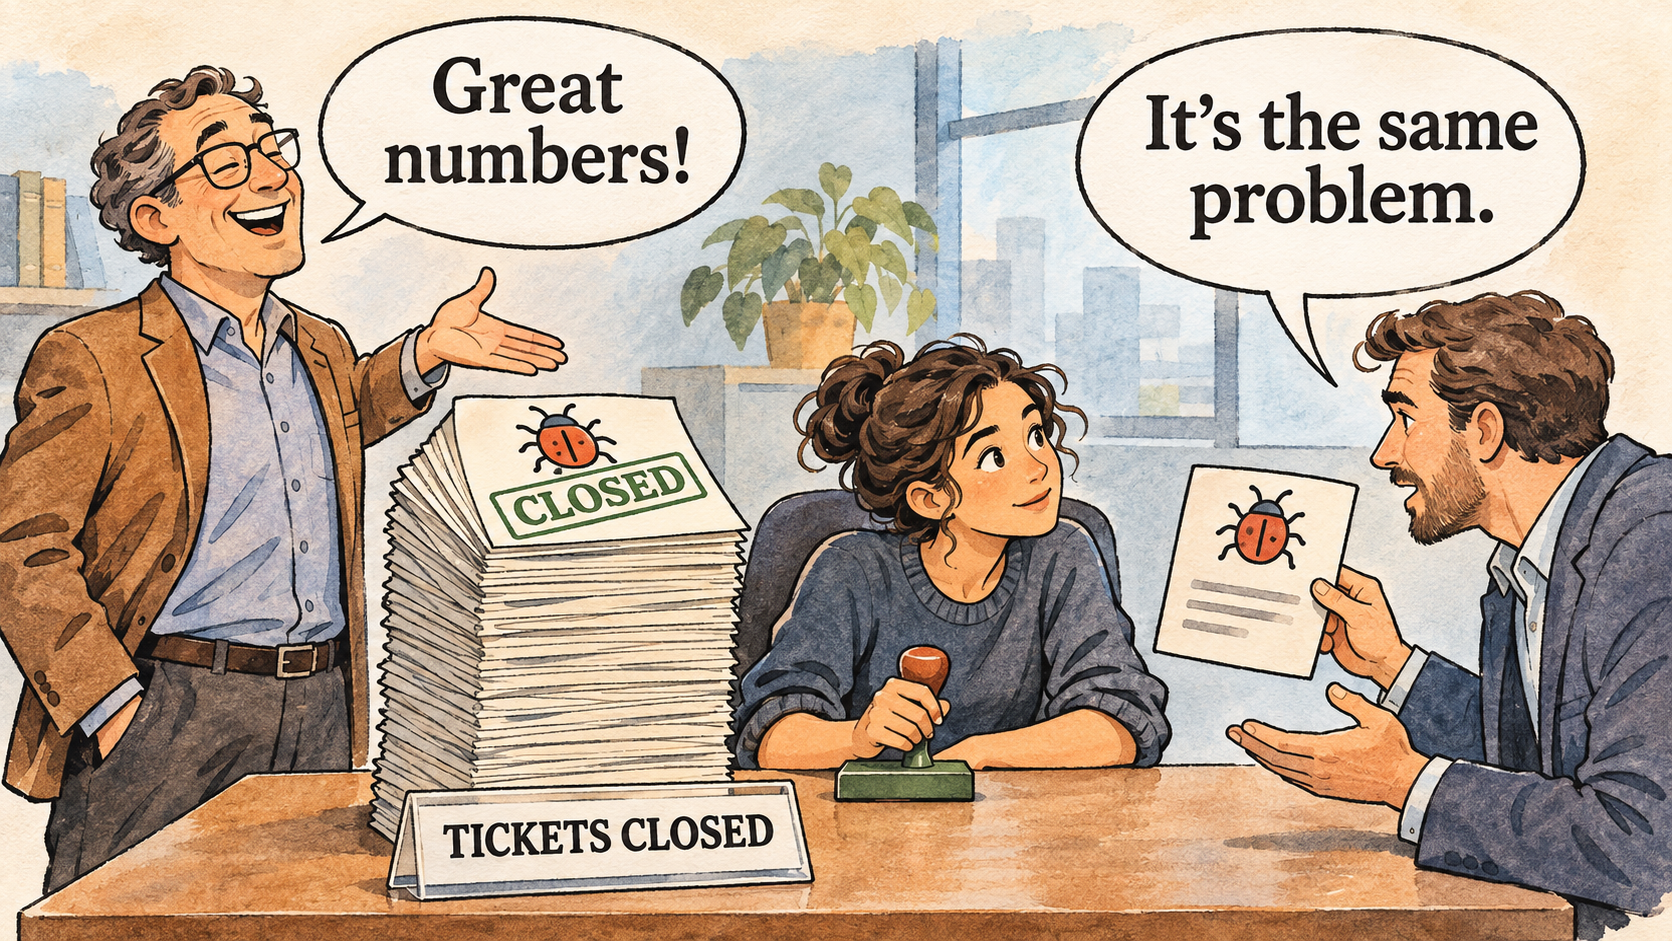
Developers were paid for each bug they fixed. That was the best solution the company had found. It looked good on paper. Dozens of tickets were closed every day, and the same problems kept coming back.
Unfortunately, when you use the wrong incentives and metrics, the metric itself becomes the goal. The developers did what they were asked to do. They closed bug tickets.
Everybody knew the underlying issues would show up again in one form or another, maybe even the next day. The metric counted how many tickets were closed. It missed the impact of each fix.
Lack of a Proper SDLC
Since everyone was firefighting, nobody was thinking about a proper software development life cycle (SDLC). No proper testing, no CI/CD, nothing. The culture was even a little hostile to those practices. The attitude was “just push it to prod.” That was it.
A developer would run a quick test, see that the fix worked, and push it to prod. That was the only check. The developers knew this was a problem, and the culture gave them little room to change it.
Lack of a Decision Chain Mindset
In The Decision Chain Mindset, I wrote about how one decision affects another. The principle is easy to understand and hard to accept. I saw that firsthand when I started leading this team.
The leadership team refused to accept that its decisions affected how people worked and blamed individuals for the problems. Fixing those problems meant fixing the system. (This is where systems thinking comes in.)
The Solution and the Results
It was obvious that the incentives and the metric weren’t working. I got rid of both. We immediately stopped measuring performance by the number of bugs closed. That was the easy part.
The second change, and the one with the biggest impact, was building a proper SDLC. We developed in the development environment and tested in staging. We would confirm that the release was ready and only after that confirmation, we would deploy it to production. The steps were simple but getting people to follow them was hard. The technical work was relatively easy, but the challenge was the culture.
I spent a huge amount of time telling people, “Testing the product is not a bad thing.” Yep, you read that right. I had to convince people that the product should be stable before it went to production. Sounds easy, right? 😉
I had to be hands-on and oversee the technical process end to end, from Git operations to setting up Kubernetes namespaces. I took an active role in the work and became part of the team I was leading.
In a couple of months, NPS rose from below zero to between 90 and 100, and the number of daily production bugs stabilized at around 10. That was a great accomplishment.
Final Thoughts
If I were back at 300 bugs a day, to be honest, I would follow the similar steps. I would start with one issue that came back after marking it as fixed. That is the kind of bug I prefer to understand. The developer closed the ticket, but the customer still had the same problem.
You, as the leader of the team, have to connect the dots, that can be a challenge because the same bug will appear as another bug in another ticket, there is where your experience plays a role.
I’d open one of those tickets, pull the PR, and the deployment record (if there’s any …). Then ask the developer why it was consider fixed when they closed the ticket? The goal is to understand the process; not to question the individual developer here. That would give away initial signs of what to change first.
Each conversation points to another clue that I would investigate.
I wrote more about tracing a change from the original request to production in Before Hiring More Developers, Find Out What Is Blocking Delivery.
When I took over, the developers were being paid to close the tickets, not to build a stable product. The developers were doing what they were asked to do. As CTO, I had to change what we asked of them and give them a way to build a product properly.
AI has been used to fix the grammar in the article.