The person behind the work
Engineer by training.
Hands-on every day.
I’m Necati Demir, a CTO and hands-on technical leader. I connect technical decisions to business priorities and stay directly involved as the team carries them through.
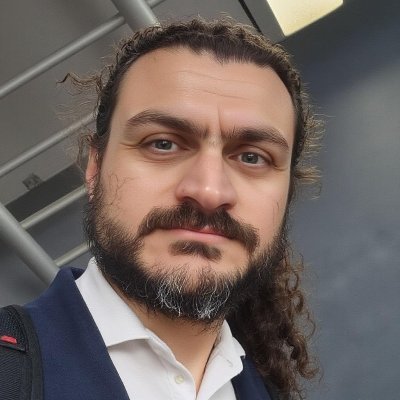
I am a PhD computer scientist with more than 20 years in software engineering and 12 years of formal team leadership.
My work spans software architecture, infrastructure, data, machine learning, and the engineering systems that bring them together. I have held CXO-level responsibility and managed teams of up to 30 people.
I stay technically involved throughout every engagement. I work directly with the team to examine architecture, investigate production problems, test assumptions, and carry decisions through implementation. That involvement keeps my judgment grounded in how the system actually works.
Following the problem across boundaries
A company often brings me in for a specific technical problem. As we investigate, the work connects to architecture, infrastructure, delivery, or the way decisions are made.
I take responsibility across those boundaries, connecting technical decisions to business priorities and making sure the work has clear ownership through to production.
That is the perspective I bring to fractional CTO work.
Building and writing
I write about software, AI, and technical leadership through the questions that come up in real work. What does a metric tell us? Who owns a decision? What happens when a prototype reaches production?
My independent projects explore the connections between models, applications, and infrastructure.
Selected work
- Decision models
BranchOne
A System One decision model for choosing among supplied candidates using text and optional image input, with workflows for training, evaluation, and inference.
- Data infrastructure
StarRocks Docker Cluster
A six-node StarRocks environment with repeatable initialization, version-specific storage, configuration management, and smoke tests.
- Model serving
Llama 3 Quantization and Serving
A workflow for quantizing Llama 3 to W8A8 and serving it through vLLM, with smoke tests and concurrent-request latency measurements.
- Local inference
Rust ONNX Chat
A Rust command-line application for running small language models locally through ONNX Runtime, with interactive and piped input.
Based in New Jersey
I work independently with software and AI companies. You can reach me directly, find my work on GitHub, or connect on LinkedIn.